
 SCOUT· 38%1h 41m·2026-11-03·Science
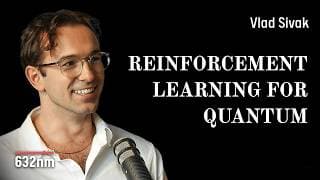
Reinforcement Learning and Quantum Decoding | Vlad Sivak Google Quantum AI
How can reinforcement learning help quantum computers learn from their own errors? In this episode, Vlad Sivak, researcher at Google Quantum AI, joins us to discuss how reinforcement learning can improve quantum computing, from error correction and decoding to the calibration of quantum hardware. Sivak explains how…
Scout bees are checking it out — divided opinions, the swarm hasn't committed.
- Platform
- 38%
- Community
- no read yet
- Value
- no read yet
Buzzmeter says it's buzzing across platforms — the Hive Vote says whether the people who actually listened liked it.
Rate this episode
Add your vote to the Hive — listeners rate every episode after they finish.
- No reviews yet — be the first.
What people are saying
“Such an interesting use case for RL, seems like it has a lot of potential”
“Could a hierarchical RL architecture preserve scalability by learning both local control policies and a smaller global policy for correlated errors?”
More from 632nm
See all episodes →

Similar episodes from other shows
More like 632nm →
Oliver Dial of IBM: Quantum Advantage Is Happening This Year

Sixty years of innovation: how would we use a quantum computer? | Masoud Mohseni
Quantum computers aren’t what you think — they’re cooler | Hartmut Neven

a16z Podcast: Quantum Computing, Now and Next
One great episode in your inbox, daily — free.
One email a day, unsubscribe anytime. No spam, ever.